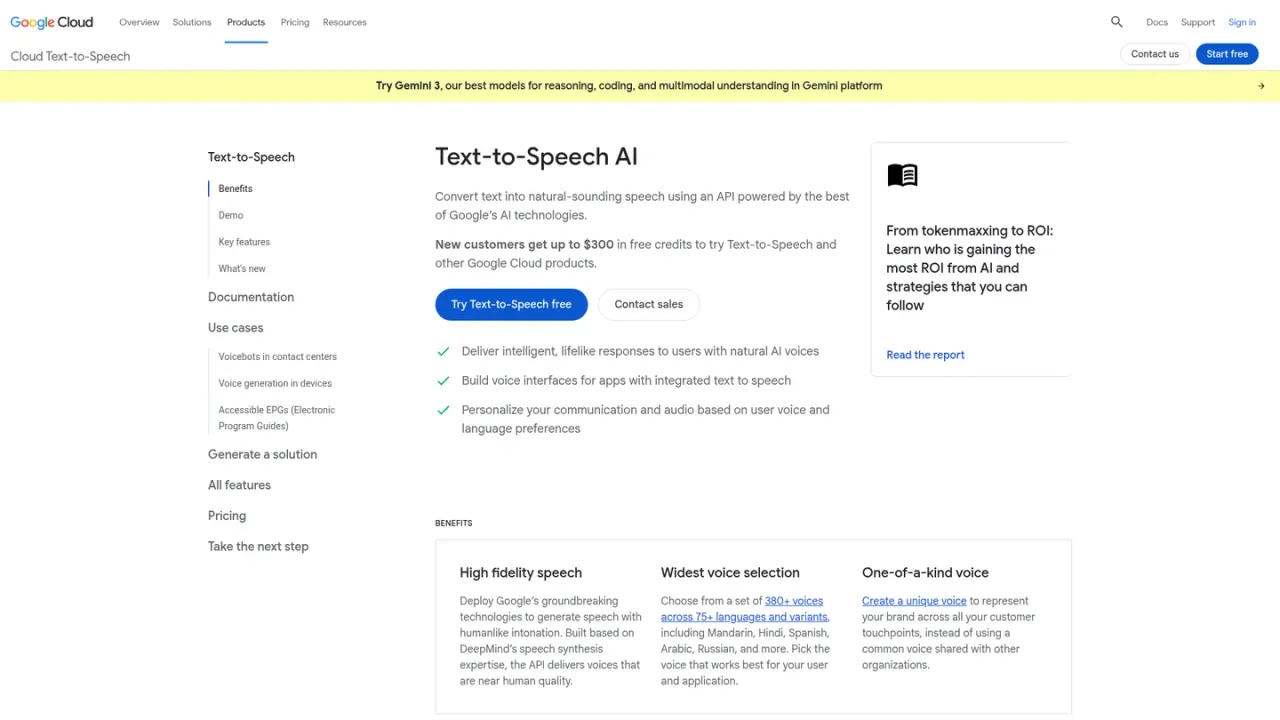
Google Text-to-Speech is a Google Cloud API that converts written text into natural-sounding speech using Google's AI speech synthesis models, including Gemini-TTS and Chirp 3: HD voices. It offers 380+ voices across 75+ languages and variants, supports plain text, SSML, and natural-language prompts for controlling style, pace, pitch, and pronunciation, and can generate single- or multispeaker audio from short snippets to long narratives. Developers integrate it via REST or gRPC APIs to build voicebots, device voice interfaces, audiobooks, and accessible program guides. Instant custom voice models can be created from as little as 10 seconds of audio. Access is usage-based with a monthly free tier for characters and paid per-character pricing beyond it; new customers receive free trial credits.
How to use Google Text-to-Speech
1
Try the demo
Enter text, select a language and voice, then click Speak It to hear synthesized audio directly on the product page.
2
Choose a model and voice
Select from Gemini-TTS, Chirp 3: HD, or other models, then pick a voice and locale from the supported voices list.
3
Control speech with SSML or prompts
Use SSML tags or natural-language style instructions to adjust pauses, pronunciation, pitch, speaking rate, and emotion where supported.
4
Integrate via API
Send REST or gRPC requests from applications or devices to synthesize audio in formats such as MP3, Linear16, and OGG Opus.
5
Create a custom voice
Use Chirp 3 instant custom voice to build a personalized voice model from as little as 10 seconds of audio input.
Google Text-to-Speech Features
Gemini-TTS with natural-language control of style, accent, pace, tone, and emotion
Chirp 3: HD voices with low-latency streaming and natural intonation
Chirp 3 instant custom voice from as little as 10 seconds of audio
380+ voices across 75+ languages and variants
SSML, plain text, and prompt-based speech control
Pitch tuning up to 20 semitones, speaking rate up to 4x faster or slower
Streaming and long audio synthesis
REST and gRPC APIs with multiple audio output formats
Google Text-to-Speech Use Cases
Building voicebots for contact centers with dynamic speech generation
Adding text-to-speech to devices and IoT products
Creating audiobooks and narrated content from text
Making electronic program guides accessible through read-aloud speech
Generating personalized audio based on user voice and language preferences
Google Text-to-Speech FAQs
It is a Google Cloud API that converts text into natural-sounding speech using Google's AI speech synthesis models, including Gemini-TTS and Chirp 3: HD voices.
The service offers 380+ voices across 75+ languages and variants, including Mandarin, Hindi, Spanish, Arabic, and Russian.
Yes. Chirp 3 instant custom voice can create personalized voice models from as little as 10 seconds of audio input, available in more than 30 locales.
Pricing is based on the number of characters sent for synthesis each month. The first 1 million characters for WaveNet voices and the first 4 million characters for Standard voices are free each month; beyond that, charges apply per 1 million characters.
New customers can receive up to $300 in free credits to try Text-to-Speech and other Google Cloud products.
You can use plain text, SSML tags, or natural-language prompts depending on the model to control pronunciation, pauses, formatting, and emotion.
Output can be generated in MP3, Linear16, OGG Opus, and a number of other audio formats.
Integration is available through REST and gRPC APIs, allowing applications and devices such as phones, PCs, tablets, cars, TVs, and speakers to request synthesized speech.
Pricing is based on characters sent for synthesis each month. WaveNet voices include 1 million free characters per month; Standard voices include 4 million free characters per month. New customers receive up to $300 in free credits. Prices in currencies other than USD follow Google Cloud SKUs.
Free tier
$0USD / month
Monthly free character allowance for Text-to-Speech synthesis before per-character charges apply.
1 million free characters per month for WaveNet voices
4 million free characters per month for Standard (non-WaveNet) voices
Access to 380+ voices across 75+ languages and variants
REST and gRPC API access
Pay-as-you-go
Price to be verified
Usage-based pricing charged per 1 million characters processed after the monthly free tier is reached.
Billed per 1 million characters of text processed
Applies after free tier is exhausted
Supports long audio synthesis up to 1 million bytes of input
Streaming audio synthesis for real-time conversations