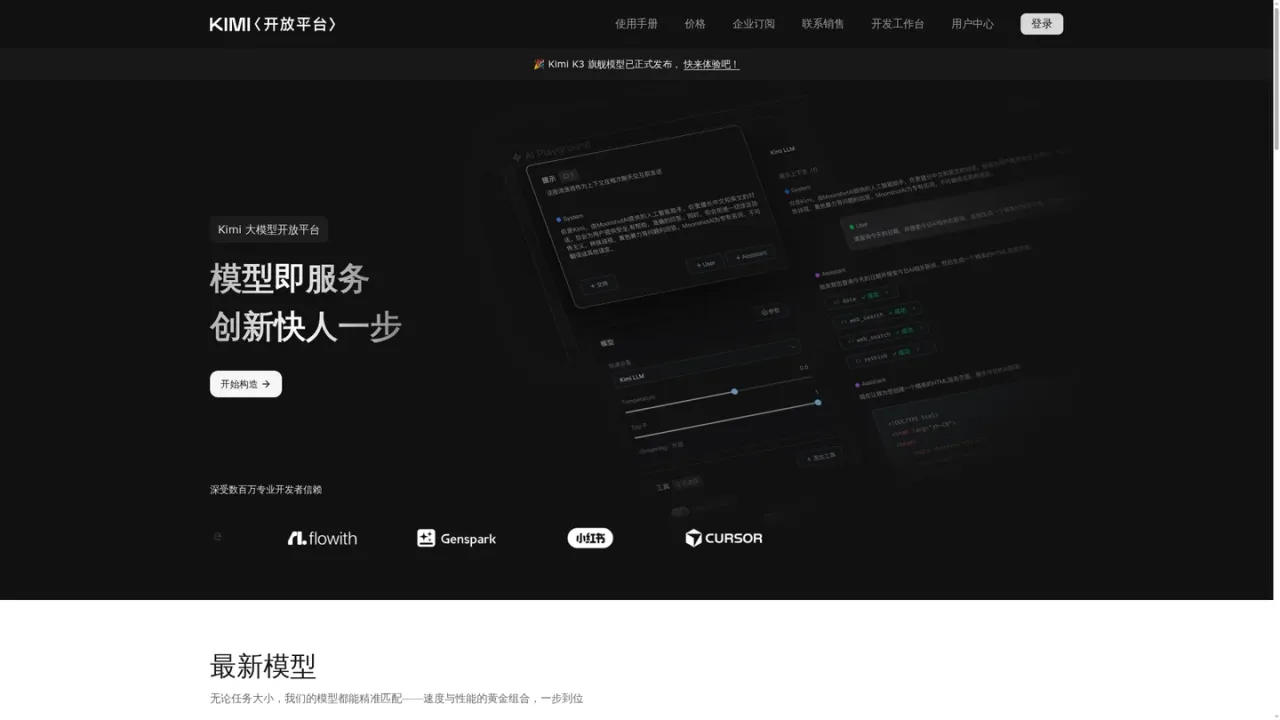
Kimi is the model-as-a-service open platform from Moonshot AI, giving developers API access to the Kimi K3, K2.7 Code and K2.6 models. It provides OpenAI-compatible Responses and Chat Completions APIs plus an Anthropic-compatible Messages API, so teams can call models over HTTP or with the OpenAI and Anthropic SDKs. Built-in official tools include web search, memory, Excel and CSV analysis, Python code execution, URL-to-markdown fetching and unit conversion. The platform targets software engineering, deep research, legal and compliance document workflows, and conversational insight analysis, with a playground for testing prompts without code. Billing is pay-as-you-go per token, with separate input, output and cache pricing; self-service top-up suits individual developers and small teams, while enterprise services add elastic rate quotas, SLA guarantees and dedicated support.
How to use Kimi
1
Create an API key
Log in to the Kimi API open platform and create and copy an API key from the API Keys page in the console.
2
Choose a model
Start with kimi-k3, or select kimi-k2.7-code or kimi-k2.6 depending on coding, speed or general-purpose needs.
3
Pick an API format
Use the OpenAI-compatible Chat Completions or Responses API, or the Anthropic-compatible Messages API, and configure the base_url.
4
Make your first call
Send a request via HTTP or the OpenAI/Anthropic SDKs using your API key, or test prompts in the playground without writing code.
Kimi Features
OpenAI-compatible Chat Completions and Responses APIs
Anthropic-compatible Messages API
Kimi K3 with 1M-token context and vision understanding
Official tools including web search, memory, Excel analysis and code runner
Playground for testing prompts without code
Pay-as-you-go token billing with cache pricing
Enterprise services with elastic rate quotas and SLA
Kimi Use Cases
Agentic coding, debugging and multi-step development
Deep research and competitive or pricing analysis
Legal and compliance document workflows such as contract review
Conversation insight and customer intent extraction
File-based question answering over uploaded documents
Kimi FAQs
The platform lists Kimi K3, Kimi K2.7 Code and Kimi K2.6, with K3 recommended as the default starting point.
No. Model inference is billed pay-as-you-go per token, and the platform states it does not offer subscription plans for model inference.
K3 input is ¥20.00 per 1M tokens on cache miss and ¥2.00 on cache hit, with output at ¥100.00 per 1M tokens.
It offers OpenAI-compatible Chat Completions and Responses APIs and an Anthropic-compatible Messages API.
Kimi K3 supports a 1,048,576-token context window.
Yes. The developer playground lets you test prompts, model behavior and sample business cases without coding.
Documented tools include web search, memory, Excel and CSV analysis, Python code execution, URL-to-markdown fetching and unit conversion.
Enterprise services list elastic rate quotas and multi-project architecture, SLA guarantees for data compliance, and priority technical support with model tuning.
Model inference is billed pay-as-you-go per token; the platform states it does not offer subscription plans for model inference. Prices are in CNY per 1M tokens.
Kimi K3
¥20.00CNY / per 1M tokens (input, cache miss)
Flagship model with a 1,048,576-token context window, designed for software engineering, knowledge work and deep reasoning. Input is ¥20.00 per 1M tokens on cache miss and ¥2.00 on cache hit; output is ¥100.00.
Coding model with a 262,144-token context window that follows instructions more reliably over long contexts. Input is ¥6.50 per 1M tokens on cache miss and ¥1.30 on cache hit; output is ¥27.00.
262,144-token context window
Input ¥6.50 / 1M tokens (cache miss)
Input ¥1.30 / 1M tokens (cache hit)
Output ¥27.00 / 1M tokens
High-speed variant available at ¥13.00 input / ¥54.00 output per 1M tokens
Kimi K2.6
¥6.50CNY / per 1M tokens (input, cache miss)
General-purpose model supporting vision and text input, thinking and non-thinking modes, and chat or coding agent tasks. Input is ¥6.50 per 1M tokens on cache miss and ¥1.10 on cache hit; output is ¥27.00.