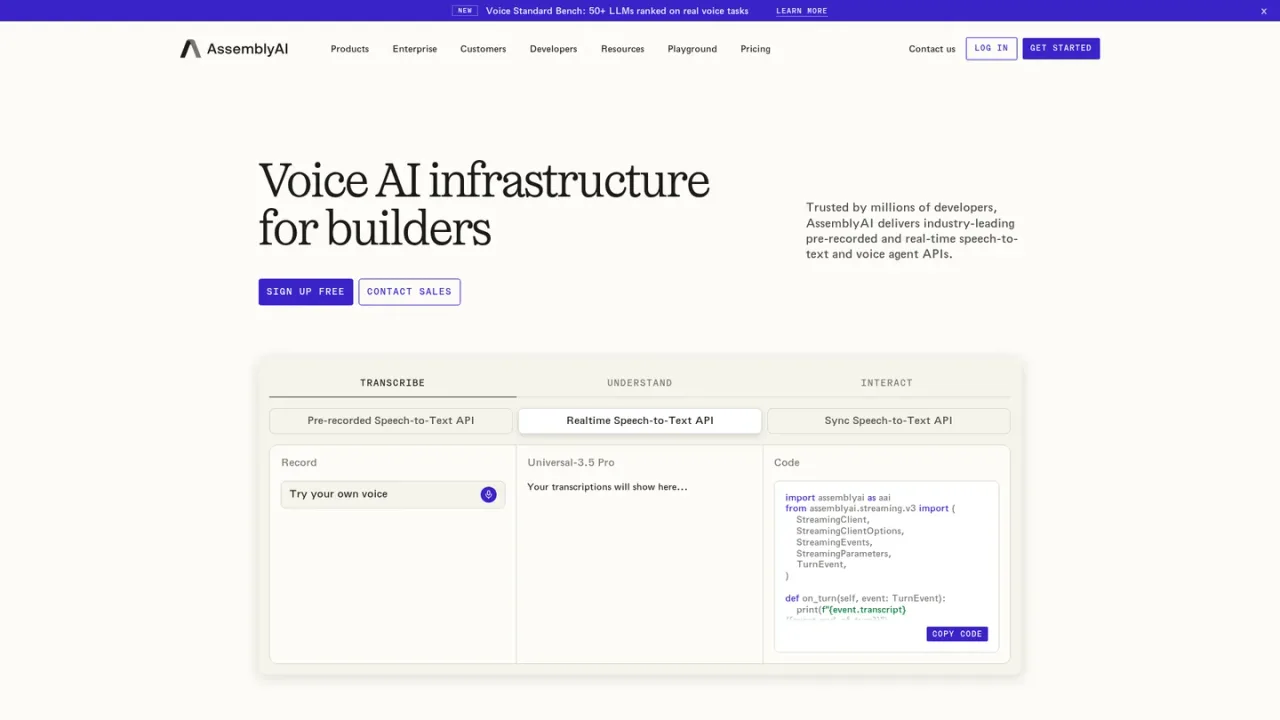
Voice AI infrastructure offering pre-recorded, streaming and sync speech-to-text, speech understanding, guardrails and voice agent APIs for developers.
AssemblyAI is a Voice AI infrastructure platform for developers building speech-driven products. Its core APIs cover pre-recorded speech-to-text across 99 languages with speaker diarization and PII redaction, streaming speech-to-text over WebSocket with roughly 150ms p50 latency for voice agents and live captions, and a synchronous API for short audio in a single request. Additional APIs add speech understanding such as summarization, sentiment and topic detection, guardrails for PII handling and content moderation, an LLM gateway, dictation and voice agent capabilities. Teams integrate through raw HTTP and WebSocket APIs, Python or TypeScript SDKs, MCP-compatible coding agents, or frameworks like LiveKit, Pipecat and Twilio. Access starts with a free sign-up, with usage-based pricing detailed on the official pricing page.
How to use AssemblyAI
1
Sign up and get an API key
Create an account through the official sign-up page and retrieve your API key from the dashboard.
2
Choose the right speech API
Pick pre-recorded, streaming, sync or dictation speech-to-text depending on whether your audio is recorded, live, short, or needs LLM formatting.
3
Integrate with SDKs or raw APIs
Use the Python or TypeScript SDK, or call the HTTP and WebSocket API reference directly for full control over requests.
4
Add speech understanding features
Enable summarization, sentiment, topic detection, speaker diarization or PII redaction on the same transcription request.
5
Test in the Playground
Try models and features in the Playground before wiring them into your production pipeline.
AssemblyAI Features
Pre-recorded speech-to-text across 99 languages with speaker diarization and PII redaction
Streaming speech-to-text over WebSocket with roughly 150ms p50 latency
Synchronous speech-to-text for short audio in a single request-response call
Dictation API that formats transcripts with an LLM in the same request
Speech Understanding API for summarization, sentiment, topic and entity detection
Guardrails API for PII handling and content moderation
LLM Gateway API for unified access to frontier language models
Python and TypeScript SDKs plus raw HTTP and WebSocket APIs
Integrations with LiveKit, Pipecat, Twilio and Langflow
Self-hosted and Voice AI Cloud deployment options
AssemblyAI Use Cases
Building real-time voice agents and live captions
Transcribing recorded calls, podcasts and meetings at scale
Generating meeting summaries and action items from transcripts
Call analytics and conversation intelligence
Medical transcription and AI scribes
Dictation features that return cleaned, formatted text
Compliance monitoring with PII redaction and content moderation
Captioning and content repurposing workflows
AssemblyAI FAQs
AssemblyAI offers pre-recorded, streaming and synchronous speech-to-text APIs, plus a Dictation API, Speech Understanding API, Guardrails API and LLM Gateway API.
The pre-recorded speech-to-text API transcribes audio and video across 99 languages, and the site lists individual language pages.
The streaming speech-to-text API handles live audio over WebSocket with roughly 150ms p50 latency, suited to voice agents and live captions.
The synchronous API transcribes audio up to 20 minutes over HTTP, or up to 120 seconds through the SDKs or when uploading while recording.
Yes. The Speech Understanding API layers summarization, sentiment, topic detection and related analysis on top of transcripts.
Yes. The Guardrails API provides PII handling and content moderation controls, and pre-recorded transcription supports PII redaction.
Developers can use raw HTTP and WebSocket APIs, Python or TypeScript SDKs, MCP-compatible coding agents, or integrations such as LiveKit, Pipecat and Twilio.
The site offers a free sign-up, and usage-based pricing details are listed on the official pricing page.
AssemblyAI is an API platform, so all prices are usage-based API rates rather than consumer subscriptions. Pre-recorded transcription is billed per audio hour submitted (multichannel billed per channel); streaming is billed on WebSocket session duration including idle time; Text-to-Speech is billed per input character; LLM Gateway is billed per million input/output tokens. Add-ons stack additively on base rates. EU region processing is the same price as US. HIPAA BAA, ISO 27001, SOC 2 Type 2, and GDPR are included with no premium pricing. The Voice Agent API is being retired and is not quoted. Legacy model values best and nano are deprecated.
Pre-recorded Speech-to-Text — Universal-3.5 Pro
$0.21USD / per hour of audio
Asynchronous transcription of recorded audio and video using the Universal-3.5 Pro model. Billed per hour of audio submitted, with add-ons stacking on the base rate.
Billed per hour of audio submitted
Add-ons such as Medical Mode (+$0.15/hr) and Speaker Diarization (+$0.02/hr) stack on the base rate
Multichannel audio is billed per channel
EU region processing is the same price as US
Pre-recorded Speech-to-Text — Universal-2
$0.15USD / per hour of audio
Asynchronous transcription of recorded audio and video using the Universal-2 model. Billed per hour of audio submitted, with add-ons stacking on the base rate.
Billed per hour of audio submitted
Supports deprecated Auto Chapters (+$0.08/hr) and Summarization (+$0.03/hr) add-ons
Multichannel audio is billed per channel
EU region processing is the same price as US
Streaming — Universal-3.6 Pro Realtime
$0.45USD / per hour of session duration
Real-time speech-to-text over WebSocket using Universal-3.6 Pro Realtime. Billed on WebSocket session duration, including idle time while the connection is open.
Billed on WebSocket session duration, not audio sent; idle time counts
Keyterms prompting included (up to 100 terms, updatable mid-stream)
Optional Voice Focus add-on (+$0.10/hr)
Streaming diarization add-on (+$0.12/hr)
Medical Mode add-on (+$0.15/hr)
Streaming — Universal-Streaming English
$0.15USD / per hour of session duration
Real-time English speech-to-text over WebSocket using Universal-Streaming English. Billed on WebSocket session duration, including idle time while the connection is open.
Billed on WebSocket session duration, not audio sent; idle time counts
Keyterms prompting add-on (+$0.04/hr, up to 100 terms)
Medical Mode add-on (+$0.15/hr, English only)
Voice Focus not supported
Streaming — Universal-Streaming Multilingual
$0.15USD / per hour of session duration
Real-time multilingual speech-to-text over WebSocket using Universal-Streaming Multilingual. Billed on WebSocket session duration, including idle time while the connection is open.
Billed on WebSocket session duration, not audio sent; idle time counts
Keyterms prompting included (up to 100 terms)
Medical Mode add-on (+$0.15/hr; EN, ES, DE, FR)
Voice Focus not supported
Text-to-Speech API — Pay as you go
$15USD / per 1M input characters
AssemblyAI-TTS-1 text-to-speech billed on the input characters sent to the API. Cloned voices and EU processing cost the same as library voices and US processing.
Billed on input characters sent to the API
Cloned voices cost the same as library voices
EU processing costs the same as US
No spend commitment required to unlock concurrency
Volume pricing and commit buyouts available via sales
LLM Gateway — GPT-5.5 (global routing)
$5.00 input / 30.00 outputUSD / per 1M tokens
Token-based access to GPT-5.5 through the LLM Gateway unified endpoint. Input and output tokens are billed at separate rates; in-region US/EU routing is 10% higher.
Separate input and output token rates
Global routing rates shown; in-region US/EU pricing is 10% higher
Prompt caching available for repeat-context savings
No separate fee for streaming, tool calling, or structured outputs
LLM Gateway — Claude 4.8 Opus (global routing)
$5.00 input / 25.00 outputUSD / per 1M tokens
Token-based access to Claude 4.8 Opus through the LLM Gateway unified endpoint. Input and output tokens are billed at separate rates; in-region US/EU routing is 10% higher.
Separate input and output token rates
Global routing rates shown; in-region US/EU pricing is 10% higher
Prompt caching available for repeat-context savings
No separate fee for streaming, tool calling, or structured outputs
LLM Gateway — Gemini 3.5 Flash (global routing)
$1.50 input / 9.00 outputUSD / per 1M tokens
Token-based access to Gemini 3.5 Flash through the LLM Gateway unified endpoint. Input and output tokens are billed at separate rates; in-region US/EU routing is 10% higher.
Separate input and output token rates
Global routing rates shown; in-region US/EU pricing is 10% higher
Prompt caching available for repeat-context savings
No separate fee for streaming, tool calling, or structured outputs
Free credits
$50USD / one-time signup credit
New accounts receive $50 in free credits at signup with no credit card required. Free-tier streaming concurrency is capped at 5 new streams per minute until upgrading.
$50 in free credits at signup
No credit card required
Free-tier streaming concurrency: 5 new streams per minute
Pay-as-you-go streaming concurrency: 100 new streams per minute