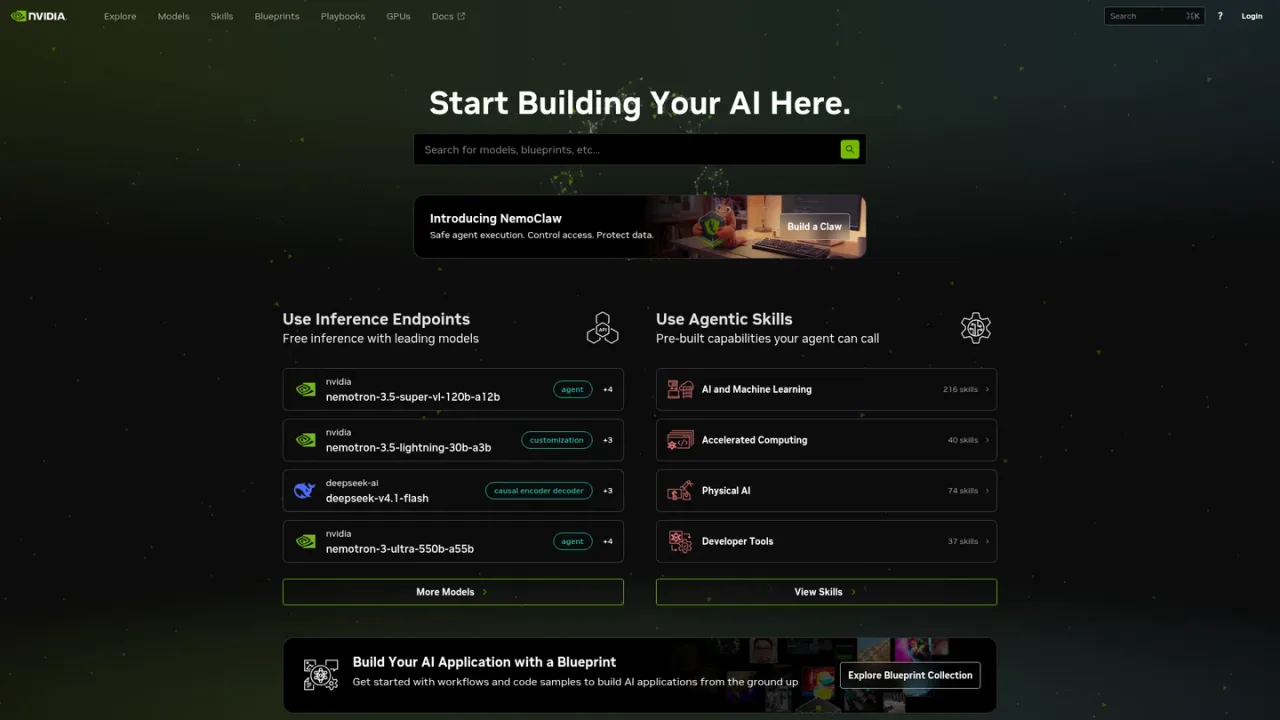
NVIDIA's platform for prototyping with free model inference endpoints, agentic skills, blueprints, and playbooks, with options to deploy NIM locally or via partners.
NVIDIA Build is a developer platform for exploring and building AI applications. It offers free inference endpoints for leading models, with rate-limited access of up to 40 requests per minute for most models and no per-token billing. Developers can browse models with benchmarks, supported tasks and context windows, call pre-built agentic skills, and start from blueprints with workflows and code samples. NemoClaw provides a sandboxed runtime for autonomous agents with policy-gated network, file and inference access. Users can prototype in their own environment, then deploy NIM containers locally, through cloud partners, or on Brev GPU instances without changing code.
How to use NVIDIA Build
1
Create and verify your account
Set up and verify an NVIDIA account to unlock full access to NVIDIA NIM APIs.
2
Generate an API key
Create an API key from the platform to authenticate your inference requests.
3
Make your first API call
Use the free inference endpoints to send your first request and test a model.
4
Prototype in your environment
Integrate the API into your own development environment and test with the playground before committing.
5
Deploy or connect to partners
Download a NIM container to run on your own cloud, use a CSP partner, or deploy on a Brev GPU instance.
NVIDIA Build Features
Free inference endpoints for leading models
Rate limits up to 40 requests per minute for most models
Model pages with benchmarks, supported tasks and context windows
Pre-built agentic skills across multiple domains
Blueprints with workflows and code samples
NemoClaw sandboxed runtime for autonomous agents
Deployment via NIM containers, CSP partners or Brev GPUs
NVIDIA Build Use Cases
Prototyping AI applications with free model inference
Testing and comparing models before integration
Building AI applications from blueprints and code samples
Running autonomous agents in a policy-gated sandbox
Deploying NIM containers to your own infrastructure
NVIDIA Build FAQs
All models on build.nvidia.com are free to prototype with. Once you hit rate limits, you can use partner endpoints or deploy a NIM locally.
The free tier runs on rate limits, up to 40 requests per minute for most models, with no per-token billing. Your personal rate limit is shown in the top-right of the dashboard.
NVIDIA states that open model inference offers the best cost-performance for most workloads, and the free tier lets you verify that before committing.
Each model page lists benchmarks, supported tasks and context window. When in doubt, use the playground to test before integrating.
Download a NIM container and run it on your own cloud, via a CSP partner such as AWS, Azure, GCP or OCI, or on a Brev GPU instance. The API is identical, so no code changes are required.
NemoClaw is a sandboxed runtime for autonomous agents. Network requests, file access and inference calls are all policy-gated, and nothing is permitted by default.
Skills are pre-built capabilities your agent can call, organized across domains such as AI and machine learning, accelerated computing, physical AI and developer tools.
Blueprints provide workflows and code samples to help you build AI applications from the ground up.