One-stop large-model API platform offering pay-as-you-go access to language, speech, image and video models, plus reserved instances and private deployment.
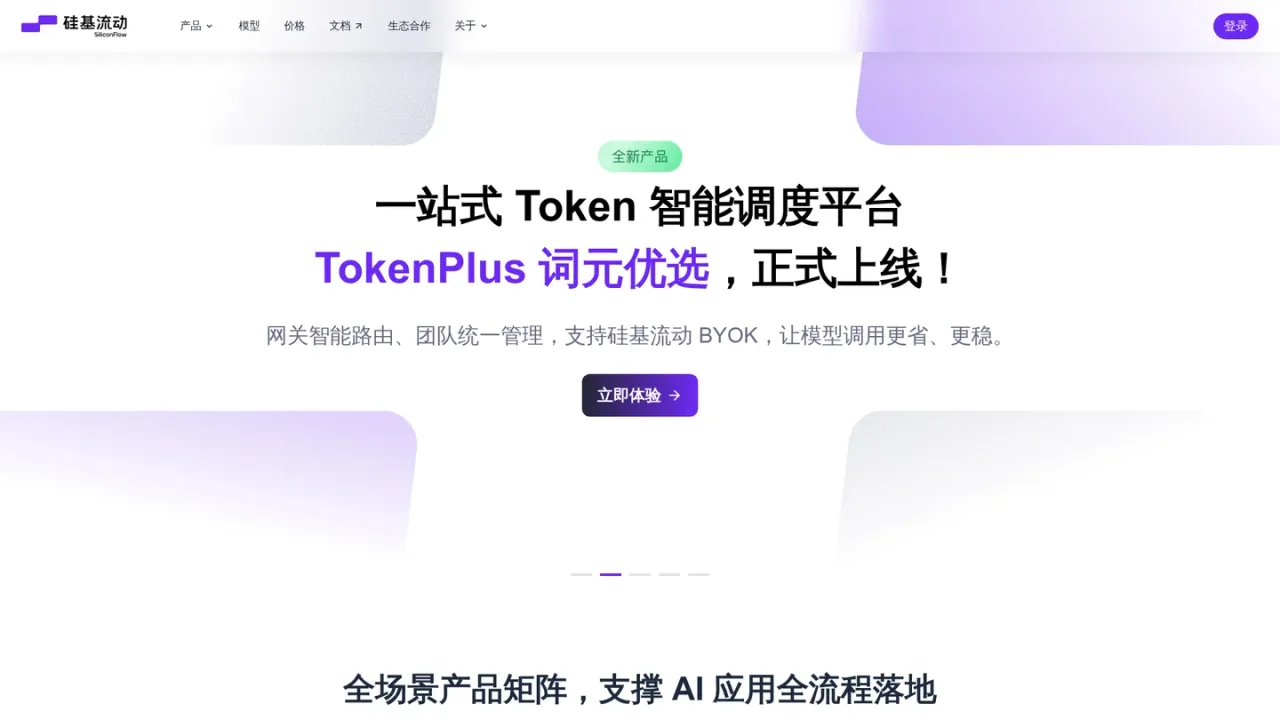
SiliconFlow is a one-stop large-model API platform for developers and enterprises building AI applications. It provides out-of-the-box APIs covering language, speech, image and video models, billed by usage, so applications can go live quickly. Beyond APIs, it offers reserved instances for core inference workloads with dedicated compute, precision guarantees and cost optimization, inference acceleration based on a self-developed engine, and private deployment for enterprise scenarios. The platform emphasizes high-speed inference, cost efficiency, stability, security and scalability, with support for BYOC deployment and domestic heterogeneous GPUs. It serves industries such as internet, education, government, intelligent computing centers and AI hardware. Access options include pay-as-you-go API usage, reserved instances, and enterprise private deployment.
How to use SiliconFlow
1
Sign in and obtain an API key
Log in to the SiliconFlow cloud console and create an API key from the account page to authenticate model calls.
2
Choose a model from the model catalog
Browse the model list and pricing page to compare input, output and cache costs across providers before selecting a model.
3
Call the API and pay by usage
Integrate the model API into your application; usage is billed by volume according to the published model prices.
4
Explore reserved instances for core workloads
For enterprise core inference scenarios, review reserved instances for dedicated compute, precision guarantees and cost optimization.
SiliconFlow Features
Out-of-the-box large-model APIs for language, speech, image and video
Pay-as-you-go billing based on published model prices
Reserved instances with dedicated compute and precision guarantees
Self-developed inference engine with cross-chip, multi-model adaptation
Private deployment and BYOC options for enterprises
Support for domestic heterogeneous GPU deployment
SiliconFlow Use Cases
Integrating language, speech, image or video model APIs into applications
Comparing input, output and cache costs across models before production selection
Running core inference workloads on reserved instances
Deploying models privately for enterprise scenarios
SiliconFlow FAQs
The platform provides APIs covering language, speech, image and video models, with a model catalog and pricing page for comparison.
API usage is billed by volume according to the published model prices; chat model prices are shown per million tokens, while image, speech and video models have their own billing units.
The pricing page lists some models as free, such as certain embedding, speech and translation models. Availability and pricing are shown on the pricing page.
Yes, the platform offers enterprise private deployment addressing model performance optimization, deployment and operations, and supports BYOC deployment.
API documentation is available at api-docs.siliconflow.cn, including a user guide introduction.
After logging in to the cloud console, you can create an API key from the account page to authenticate model calls.
The platform lists solutions for internet, education, government, intelligent computing centers and AI hardware scenarios.
Prices are per million tokens for chat models unless otherwise stated; some models are listed as free. Image, speech and video models are billed per image, per second or per video as shown on the pricing page. Reserved instances and private deployment are quoted separately.
Pay-as-you-go API
CNY / per usage
Usage-based access to large-model APIs covering language, speech, image and video scenarios. Billing follows the published per-model prices.
Out-of-the-box APIs for language, speech, image and video models
Billed by usage according to model prices
Some models listed as free on the pricing page
Model prices shown per million tokens for chat models
Reserved Instances
CNY / contact for quote
Dedicated compute for enterprise core inference scenarios, with precision guarantees and cost optimization.
Dedicated compute for core inference workloads
Precision guarantees
Cost optimization for high-usage scenarios
Enterprise-grade SLA support
Private Deployment
CNY / contact for quote
Enterprise private deployment addressing model performance optimization, deployment and operations.