DeepSeek
DeepSeek Open Platform provides API access to the DeepSeek V4 series for building applications, with API docs and web search and fetch support.
AI Coding & Website Builders ToolsNot specified
AI Coding Assistant
PRODUCT OVERVIEW
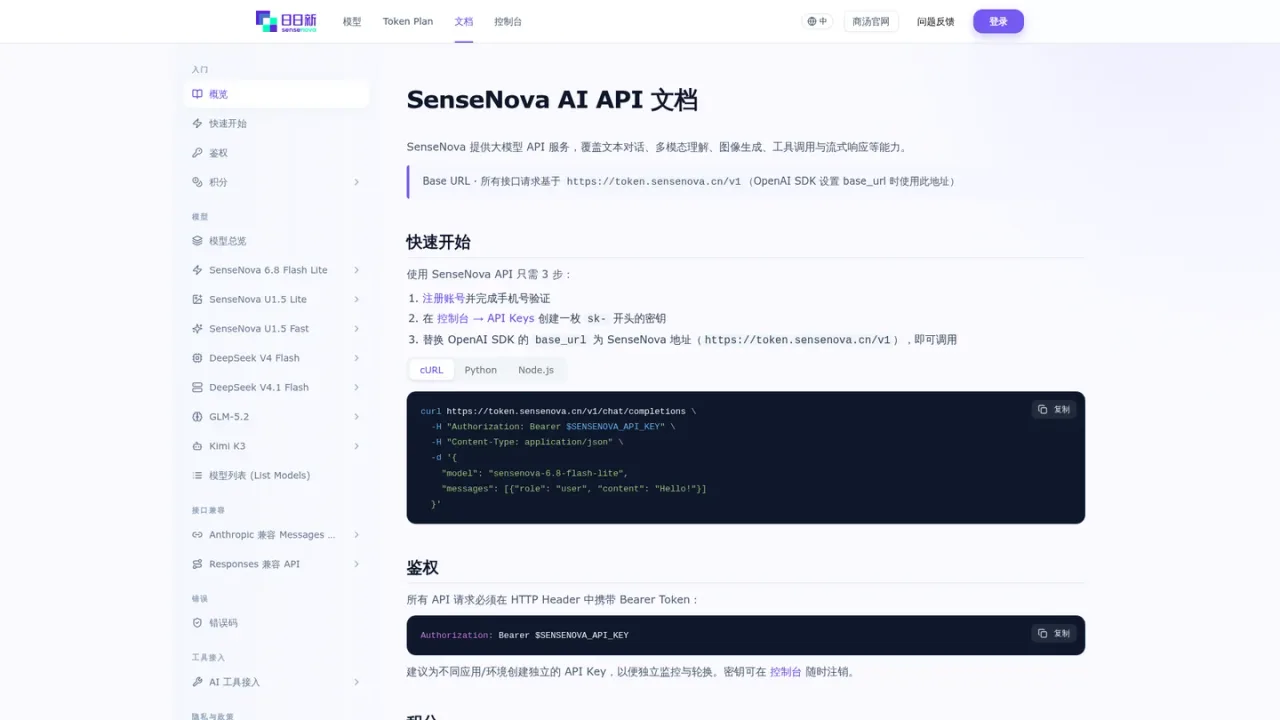
SenseNova is SenseTime's large-model API platform, documented at platform.sensenova.cn. It exposes chat completions, multimodal image input, image generation and editing, function calling, streaming responses and structured JSON output through an OpenAI-compatible base URL, so developers can point existing SDKs at SenseNova with a Bearer API key. The model lineup includes SenseNova 6.8 Flash Lite for multimodal agent tasks and data analysis, SenseNova U1.5 Lite and U1.5 Fast for image creation, plus third-party models such as DeepSeek, GLM and Kimi. It targets developers and teams building agents, coding helpers and content pipelines. Access requires registration and an API key; TokenPlan credits are documented in a public beta.
Create an account on the SenseNova platform and complete phone verification.
In the console, open API Keys and generate a key beginning with sk-.
Set the OpenAI SDK base_url to https://token.sensenova.cn/v1 and send requests with a Bearer token.
Send a chat completions request specifying a model such as sensenova-6.8-flash-lite, optionally with images, tools or streaming.
Building multimodal agents that plan, call tools and verify results
Complex data analysis and presentation generation
Text-to-image creation and reference-based image editing
Coding assistance and long-context engineering tasks
Adding chat and vision capabilities to existing OpenAI SDK apps
All API requests use https://token.sensenova.cn/v1, which can be set as the base_url in the OpenAI SDK.
Every request must include an Authorization header with a Bearer token created in the console under API Keys.
The documented lineup includes SenseNova 6.8 Flash Lite, SenseNova U1.5 Lite, SenseNova U1.5 Fast, DeepSeek V4 Flash, DeepSeek V4.1 Flash, GLM-5.2 and Kimi K3.
Yes. SenseNova 6.8 Flash Lite accepts images as a public URL or a Base64 data URL in JPG, JPEG, PNG or WebP format.
Yes. You declare tools in the request, the model returns tool_calls, and you send results back with role tool and the matching tool_call_id.
Thinking is enabled by default and can be tuned with reasoning_effort from low to max, or turned off with none.
TokenPlan accounts use general credits plus Flash-Lite exclusive credits, with rolling 5-hour and weekly quotas during the public beta.
Yes. Setting response_format to json_object makes the model return JSON, and the docs advise including the json keyword in your prompt.
The supplied pages describe TokenPlan credits in a public beta with rolling 5-hour and weekly quotas, but no plan prices are listed.
See the official website for current pricing.
COMMUNITY REVIEWS
No reviews yet.
DeepSeek Open Platform provides API access to the DeepSeek V4 series for building applications, with API docs and web search and fetch support.