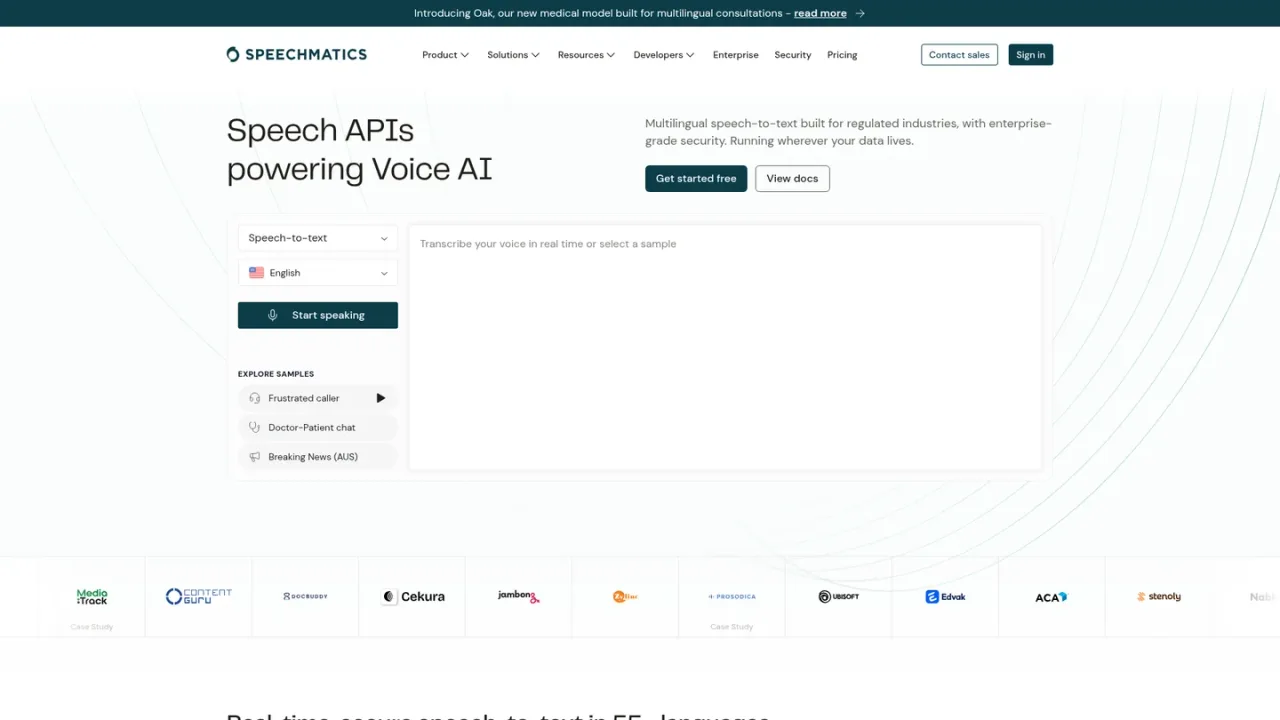
Speechmatics provides speech-to-text APIs for developers and enterprises, converting live or recorded audio into text for captions, analytics, records and voice AI. It offers real-time transcription with sub-second latency, pre-recorded batch transcription, speaker diarization, custom dictionaries and word-level timings across 55+ languages, including mixed-language and code-switching audio. Specialized models cover clinical dictation (Oak) and conversational voice agents (Linden). Deployment options include cloud, on-premise and on-device, with compliance certifications such as HIPAA, GDPR, SOC 2 and ISO 27001. Access starts with $100 in free credits, then usage-based pricing from $0.12 per hour.
How to use Speechmatics
1
Create an account
Sign up at the Speechmatics portal to receive $100 in free credits with no card required.
2
Choose a model and mode
Select a model such as Melia 1, Enhanced, Oak 1 or Linden 1, and choose pre-recorded or real-time transcription.
3
Integrate via API
Use the documented API and SDKs to send audio files or live streams and receive transcripts with features like speaker diarization and word timings.
4
Monitor usage and scale
Track credit consumption in the dashboard and move to pay-as-you-go, credit packs or a subscription as usage grows.
Speechmatics Features
Real-time speech-to-text with sub-second latency
Pre-recorded batch transcription from audio or video files
55+ languages with mixed-language and code-switching support
Speaker diarization and word-level timings
Custom dictionary and smart formatting
Medical model for clinical language (Oak 1)
Voice agent model with turn detection (Linden 1)
Cloud, on-premise and on-device deployment options
HIPAA, GDPR, SOC 2 Type II and ISO 27001 compliance
Speechmatics Use Cases
Live captioning for broadcasts, events and sports
Medical dictation and ambient clinical scribes
AI voice agents and conversational platforms
Contact center analytics and agent productivity
Legal transcription for court reporters and law firms
Automated meeting notes and searchable lesson summaries
Media monitoring and speech analytics
Speechmatics FAQs
A speech-to-text API converts spoken audio into written text inside an app, product or workflow. Speechmatics processes recorded files or live audio and returns transcripts for captions, search, analytics, records and voice AI.
Yes. New accounts get $100 in credit with no card required, so you can test transcription quality and language support before moving to a paid plan.
55+ languages, with coverage across accents, dialects and code-switching where speakers move between languages mid-sentence.
Yes. Speaker diarization identifies and separates individual speakers in meetings, calls, legal proceedings and healthcare consultations.
Pricing is usage-based. You buy credits (1 credit = $1 before discounts), and usage consumes them down to the second at an hourly rate.
On a subscription, overages are billed at your discounted rate at month end. Otherwise, with a card on file, overages are billed at the base rate. On the free tier, API access is paused once credits run out.
Yes. Speechmatics supports cloud, on-premise and on-device deployment and is ISO 27001, GDPR, HIPAA and SOC 2 Type II compliant.
The free usage tier provides two concurrent real-time connections, the Pro tier supports 50 concurrent streams, and Enterprise customers can have as many connections as required.
Usage-based pricing in USD credits (1 credit = $1 before discounts). New accounts receive $100 in free credits with no card required. Model-training opt-in gives 33% off speech-to-text rates; volume discounts up to 25% off every credit.
Free tier
$0USD / one-time credit
New accounts receive $100 in credits to test transcription quality and language support before paying.
$100 in sign-up credits, no card required
Two concurrent real-time connections
API access paused once credits run out
Melia 1 (pre-recorded)
$0.12USD / per hour
Next-generation multilingual model for pre-recorded audio that transcribes 56 languages without choosing one up front.
Multilingual and mixed-language audio
Code-switching support
Speaker diarization
Language hints and labeling
Smart formatting and word-level timings
Enhanced (pre-recorded)
$0.38USD / per hour
Highest-accuracy pre-recorded model for single-language audio where maximum accuracy matters.
Highest accuracy
Custom dictionary
Advanced punctuation and smart formatting
Speaker diarization
Word-level timings
Oak 1 (pre-recorded)
$0.15USD / per hour
Medical model for clinical conversations and dictation, covering drug names, dosages, abbreviations and procedure terms.
Clinical language transcription
Full multilingual support
Mixed-language transcription
Speaker diarization
Smart formatting
Standard (pre-recorded)
$0.23USD / per hour
Cost-effective model for high-volume, cost-sensitive workloads with the same features as Enhanced at lower accuracy.
Cost-efficient rate
Custom dictionary
Speaker diarization
Smart formatting
Word-level timings
Melia 1 (real-time)
$0.20USD / per hour
Real-time multilingual model for live audio, transcribing 56 languages and switching mid-sentence.
Real-time multilingual transcription
Mixed-language and code-switching support
Language hints and labeling
Smart formatting
Word-level timings
Enhanced (real-time)
$0.40USD / per hour
Highest-accuracy real-time model for single-language live audio where maximum accuracy is required.
Highest real-time accuracy
Custom dictionary
Speaker diarization
Smart formatting
Word-level timings
Oak 1 (real-time)
$0.23USD / per hour
Real-time medical model for live clinical conversations and dictation.
Real-time clinical transcription
Full multilingual support
Mixed-language transcription
Speaker diarization
Smart formatting
Linden 1 (real-time)
$0.15USD / per hour
Voice agent model with built-in turn detection for conversational, low-latency use cases.
Built-in turn detection
Low-latency live transcription
Speaker diarization
Custom dictionary
Smart formatting
Standard (real-time)
$0.23USD / per hour
Cost-effective real-time model for high-volume, cost-sensitive live workloads.